Starting point: Conditioning and mutual information, density operators and POVMs; trace distance is introduced through decision probabilities.
Keep in view: Distinguish two nonorthogonal qubit states with specified prior probabilities.
We can now describe every measurement a receiver could make. Its outcome probabilities come from a POVM, and its effect on the system from an instrument. With that in hand we can return to the question that started the course: how well can a receiver tell two preparations apart?
For cards and lamps the answer came from a table of counts. For two nonorthogonal quantum states, such as \(\ket0\) and \(\ket+\), the receiver also chooses the measurement, and the possible measurements form a continuum. Which one is best, and how good is it? We first fix the task: priors, a decision rule and a criterion for success. Scanning a family of readouts finds a good measurement. The eigenvectors of one matrix then prove that no POVM does better, and the same matrix defines the trace distance. Changing the criterion to forbid mistakes gives a different optimum. Scoring by bits instead of correct guesses gives the accessible information.
8.1 Discrimination Tasks
Alice prepares \(\ket0\) or \(\ket+\) with equal probability and gives Bob the qubit. Bob knows the two candidates but not which was sent. What should he count as doing well? We first score a simple strategy, which shows how priors, decisions and errors define the task. Then we ask why no strategy we have tried is ever perfect for this pair.
Label the candidates 0 for \(\ket0\) and 1 for \(\ket+\). Without measuring, Bob can always guess 0 and be right half the time. Can a measurement beat one half?
Try a Z measurement, guessing label 0 on outcome 0 and label 1 on outcome 1. On input \(\ket0\) the outcome is always 0. On input \(\ket+\) the outcomes are 0 and 1 with probability \(1/2\) each. With equal priors the joint weights are
where the first entry is the label and the second the outcome. Bob is right on the weights \(p(0,0)\) and \(p(1,1)\), so his success probability is \(1/2+1/4=3/4\).
The two outcomes are not equally informative. Outcome 0 leaves both labels possible, with posterior \((2/3,1/3)\), and guessing 0 is merely the better bet. Outcome 1 can only come from plus, so it identifies the input with certainty. Certainty on some trials is not perfect discrimination on all of them.
The score depends on choices we must state. The priors could be unequal, and then the baseline is the more likely label, not one half. Bob might be allowed to say "I don't know", or forbidden to make any mistake. Each choice defines a different optimization problem.
For \(\ket0\) and \(\ket1\), a Z measurement is never wrong. Why is our pair harder?
Orthogonal states can be read by a measurement in a basis that contains both, and each then gives its own outcome with certainty. Our states are not orthogonal. Their overlap is \(s=|\braket0+|=1/\sqrt2\). Consider any projective test that always passes \(\ket0\). It must keep the direction \(\ket0\), so plus passes it with probability at least \(s^2=1/2\). Whenever plus passes, Bob would wrongly say zero.
That argument covers projective tests only. A POVM can have effects that are not projectors. Could some cleverer measurement separate a nonorthogonal pair perfectly, or at least beat every projective one? To answer, we need the best possible success over all measurements.
Problems
Problem 8.1. For the Z strategy, what is the posterior probability of label zero after outcome zero?
Worked solution
The outcome-zero weight from input zero is 1/2; its total weight is 3/4. The posterior is (1/2)/(3/4)=2/3. Guessing zero is best for this outcome but is not certain to be right.
8.2 Optimal Strategies
The Z measurement succeeds three times in four. What is the best success any measurement can reach, and which measurement reaches it? We first rotate the readout and find a better angle. Writing success in terms of one matrix then explains that angle and proves it optimal among all POVMs, which defines the trace distance. Finally we change the rules, forbidding errors but allowing an inconclusive answer, and find a different best measurement.
The Z measurement favours zero: it never errs on zero and errs on half the pluses. Rotating the readout might balance the errors. Let Bob guess zero when a projective test for \(\ket{v_\theta}=\cos\theta\ket0+\sin\theta\ket1\) passes, and plus when the perpendicular test passes. His success is
At \(\theta=0\) we recover \(3/4\). The bracket is largest, \(\sqrt2\), at \(\theta=-\pi/8\), giving success \(1/2+\sqrt2/4\approx0.8536\). Why that angle, and can a POVM beat it?
Write the success of any two-outcome POVM. Let \(E\) be the effect for guessing 0 and \(I-E\) the effect for guessing 1. With priors \(p_0,p_1\) and states \(\rho_0,\rho_1\),
Everything Bob controls is in \(\mathrm{tr}(E\Delta)\). For our pair, \(\Delta=\tfrac12(\ket0\bra0-\ket+\bra+)=\tfrac14\bigl(\begin{smallmatrix}1&-1\\-1&-1\end{smallmatrix}\bigr)\). This matrix has trace 0 and determinant \(-1/8\), so its eigenvalues are \(\pm1/(2\sqrt2)\). Direct multiplication shows that the eigenvector for \(+1/(2\sqrt2)\) is \(\ket{v_{-\pi/8}}\), the best direction found by scanning.
That is no coincidence. Let \(\ket{v_+}\) and \(\ket{v_-}\) be the two eigenvectors, which are orthogonal. Then \(\Delta=\lambda_+\ket{v_+}\bra{v_+}+\lambda_-\ket{v_-}\bra{v_-}\), and
Both \(E\) and \(I-E\) are positive, so each \(\bra vE\ket v\) lies between 0 and 1. The sum is largest when the positive eigenvalue gets weight 1 and the negative one gets weight 0. The projector \(E=\ket{v_+}\bra{v_+}\) does exactly that, and no effect does better. So \(P_{\rm succ}\leq\tfrac12+\tfrac1{2\sqrt2}\approx0.8536\) for every measurement, and the rotated readout attains it.
The argument works for any two density operators, given one fact we quote from linear algebra. A Hermitian matrix, such as \(\Delta\), has real eigenvalues and an orthonormal basis of eigenvectors. The best \(E\) projects onto the eigenvectors with positive eigenvalues, so the best success is \(p_1\) plus the sum of the positive eigenvalues. Since the eigenvalues add to \(\mathrm{tr}\,\Delta=p_0-p_1\), this becomes
where the trace norm \(\|\Delta\|_1\) is the sum of the absolute values of the eigenvalues. This is the Helstrom bound, after Carl Helstrom, who derived it in the 1960s.
With equal priors, \(\Delta=(\rho_0-\rho_1)/2\). The trace distance \(T(\rho,\sigma)=\tfrac12\|\rho-\sigma\|_1\) then gives \(P_{\rm succ}^{\max}=(1+T)/2\). Its meaning is operational. At \(T=0\) every measurement gives identical statistics, and Bob cannot beat a guess. At \(T=1\) he can be certain.
For two pure states with overlap \(s\), the trace distance has a closed form. In the plane they span, write \(\ket\phi=s\ket\psi+\sqrt{1-s^2}\ket{\psi_\perp}\), choosing phases so that \(s\geq0\). The difference of their projectors has trace 0 and determinant \(-(1-s^2)\), so its eigenvalues are \(\pm\sqrt{1-s^2}\), and \(T=\sqrt{1-s^2}\). For zero and plus, \(T=1/\sqrt2\), which agrees with the 0.8536 above. This also answers the earlier question: whenever \(s>0\), \(T<1\), so no measurement of any kind separates nonorthogonal pure states perfectly.
Choose a decision basis
Predict first. Compare the original Z measurement with a rotated one. Change the prior and predict whether the equal-prior angle stays optimal.
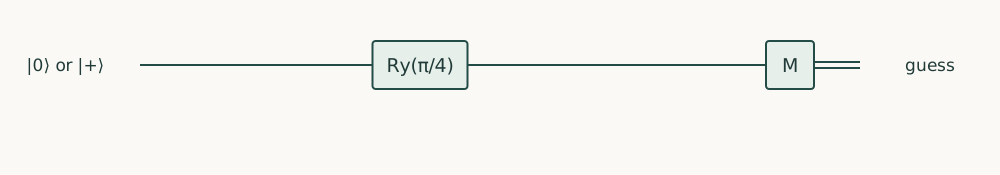
The zero-guess vector is \(\cos\theta\ket0+\sin\theta\ket1\). Equal priors give success 0.7500 at \(\theta=0\) and about 0.8536 at \(\theta=-22.5°\). The circuit above implements the latter readout. Unequal priors change the optimum.
Minimum-error discrimination for equal-prior zero and plus. After this rotation, guess zero for outcome zero and plus for outcome one.
To build the optimal readout, rotate the qubit by \(\pi/8\) so that \(\ket{v_+}\) becomes \(\ket0\), then measure Z. The drawing labels this rotation with the angle \(\pi/4\), following a common convention that writes rotation angles doubled.
8.2.2 Unambiguous discrimination and inconclusive results§
Suppose a wrong answer is costly but "inconclusive" is acceptable. The Z measurement already gave a hint: its outcome 1 identified plus with certainty. Can Bob also have an outcome that identifies zero with certainty?
An effect that never fires on plus must vanish on \(\ket+\), so it must be proportional to \(\ket-\bra-\). An effect that never fires on zero must be proportional to \(\ket1\bra1\). Try
How large can \(c\) be? The remainder must be a valid effect. In the computational basis, \(E_?=\bigl(\begin{smallmatrix}1-c/2&c/2\\c/2&1-3c/2\end{smallmatrix}\bigr)\). A two-by-two Hermitian matrix is positive when its diagonal entries and its determinant are nonnegative. The determinant is \(1-2c+c^2/2\), which first reaches zero at \(c=2-\sqrt2\approx0.586\). That is the largest allowed \(c\).
With this choice, zero gives a conclusive answer with probability \(\bra0E_0\ket0=c/2=1-1/\sqrt2\approx0.293\), and plus does too. Bob never errs, but he is inconclusive on about 71% of trials. Notice that \(1-1/\sqrt2=1-s\). For two equal-prior pure states, \(1-s\) is the best possible conclusive probability; we quote this optimality (due to Ivanovic, Dieks and Peres) rather than prove it. Compared with the minimum-error measurement, Bob trades many more non-answers for the guarantee that every answer is right.
Problems
Problem 8.2. Why does E0 give no false identification on plus?
Worked solution
Minus is orthogonal to plus, so 〈+|E0|+〉=0. Positivity ensures this is a valid zero probability, not cancellation between negative probabilities.
8.3 Accessible Information
Success probability scores a single guess. If Alice uses the two states to send a stream of bits, the natural score is how many bits per qubit reach Bob. How do we compute that, and is there a limit? We turn each measurement into a classical channel and use mutual information. Then we evaluate two measurements and state the ceiling that holds for any encoding into one qubit.
Alice encodes a label \(x\), chosen with probability \(p_x\), in a state \(\rho_x\). Bob measures with a POVM \(\{E_y\}\). What do label and outcome look like together?
They form an ordinary joint table:
\[p(x,y)=p_x\,\mathrm{tr}(E_y\rho_x).\]
The states and the measurement together act as a classical channel from \(x\) to \(y\). So we can use the classical score: the mutual information \(I(X:Y)=H(X)-H(X\mid Y)\), the average reduction in Bob's uncertainty about the label. The largest value over all of Bob's measurements is the accessible information of the encoding.
Is the measurement that maximizes correct guesses the one that maximizes bits? Not necessarily. Success counts right answers. Mutual information also rewards outcomes that shift the posterior without settling it. The two optimizations can have different answers.
How many bits do our two measurements extract from zero and plus? Start with the optimal decision readout. It errs on each label with the same probability \(q=(1-1/\sqrt2)/2\approx0.146\). With a fair input, that makes it a binary symmetric channel. Its mutual information is \(1-h_2(q)\approx0.399\) bits per qubit.
For the Z measurement, outcome 0 has probability \(3/4\) and posterior \((2/3,1/3)\), while outcome 1 settles the label. So \(H(X\mid Y)=\tfrac34h_2(1/3)\), and \(I(X:Y)=1-\tfrac34h_2(1/3)\approx0.311\) bits. Here the better decision measurement also extracts more bits, though that need not hold in general. For two equal-prior pure states it is known that this symmetric readout maximizes the mutual information too (a result of Levitin, 1995), so 0.399 bits is the accessible information of this encoding.
Does a better encoding have a ceiling? A qubit's amplitudes take continuously many values, so one might hope to pack many bits into them. We quote a theorem that rules this out, due to Holevo: however Alice encodes classical labels in one qubit, and however Bob measures it, the accessible information is at most one bit. Orthogonal states reach that bit. The general form of the bound uses quantum entropy, which we have not yet built.
Two copies are a different matter. If Alice sends two copies of her state, Bob faces the pair \(\ket{00}\) versus \(\ket{++}\), whose overlap is smaller, and he can do better. One copy is a fixed resource. Could Bob make his own second copy from it?
Problem 8.3. If one state has prior 0.99, is a fair guess the right baseline?
Worked solution
No. Always guessing the common state already succeeds with probability 0.99. Any claimed improvement must use the specified priors.
Transfer problem. Bob receives two independent copies of the same hidden preparation, either zero or plus with equal priors. Use their overlap to compute the optimal decision success. Where did the second copy come from, and why does that matter?
Worked solution
The joint candidates have overlap \((1/\sqrt2)^2=1/2\). The equal-prior pure-state trace distance is \(\sqrt{1-s^2}=\sqrt3/2\), so optimum success is \((1+\sqrt3/2)/2\approx0.9330\). Alice supplied two copies; Bob has not manufactured a second copy from an unknown single input.
Summary
Non-orthogonal quantum states \(\langle\psi_0|\psi_1\rangle \neq 0\) cannot be distinguished with zero error in a single copy.
Minimum-error discrimination between two states is solved by the Helstrom bound \(p_{\mathrm{succ}} = \frac{1}{2}\bigl(1 + \|p_0\rho_0 - p_1\rho_1\|_1\bigr)\), achieved by projecting onto the positive and negative eigenspaces of \(p_0\rho_0 - p_1\rho_1\).
Unambiguous state discrimination uses a three-outcome POVM to eliminate false identifications completely at the price of an inconclusive outcome occurring with probability at least \(|\langle\psi_0|\psi_1\rangle|\).
Questions and worked problems
These exercises draw on the whole chapter. Attempt each question before opening a hint, explain your reasoning, then compare it with the worked solution.
Using \(T=\sqrt{1-s^2}\) for pure states with overlap magnitude \(s\), find the trace distance and the optimal equal-prior success probability for the pairs (a) \(\ket0,\ket1\); (b) \(\ket+,\ket{y_+}\) with \(\ket{y_+}=(\ket0+i\ket1)/\sqrt2\); (c) \(\ket0\), \(\cos\frac\pi8\ket0+\sin\frac\pi8\ket1\).
Hint 1
\(|\braket{+}{y_+}|=|1+i|/2\).
Hint 2
Equal-prior success is \((1+T)/2\).
Worked solution
(a) \(s=0\), \(T=1\), success \(1\). (b) \(s=|1+i|/2=1/\sqrt2\), \(T=1/\sqrt2\), success \(\approx0.854\): the same as \(\ket0\) and \(\ket+\), since only the overlap matters. (c) \(s=\cos\frac\pi8\approx0.924\), \(T=\sin\frac\pi8\approx0.383\), success \(\approx0.691\). Closer states are harder to tell apart, and the overlap magnitude alone fixes the optimum for two equally likely pure states.
For equal priors, compare the minimum-error success \((1+\sqrt{1-s^2})/2\) with the unambiguous success \(1-s\) for \(\ket0,\ket+\) and for \(\ket0,\ket1\). Which task is harder, and what does the unambiguous strategy give in exchange?
Hint 1
For \(\ket0,\ket+\), \(s=1/\sqrt2\).
Hint 2
Unambiguous discrimination never errs but may be inconclusive.
Worked solution
For \(\ket0,\ket+\): minimum-error success \(\approx0.854\) with error \(\approx0.146\); unambiguous success \(1-\frac{1}{\sqrt2}\approx0.293\), never wrong, inconclusive \(\approx70.7\%\) of the time. For \(\ket0,\ket1\): both give \(1\). Forbidding errors costs a lot when the states overlap: the unambiguous strategy gives certainty about the answer on the trials where it does answer, which the minimum-error strategy never provides for any individual trial.
Find the trace distance between \(\ket0\bra0\) and \(I/2\), and the optimal equal-prior success probability for telling them apart. Which measurement achieves it?
Hint 1
\(\rho-\sigma=\mathrm{diag}(\frac12,-\frac12)\).
Hint 2
\(T=\frac12\|\rho-\sigma\|_1\).
Worked solution
\(\rho-\sigma=\mathrm{diag}(\frac12,-\frac12)\), whose absolute eigenvalues sum to \(1\), so \(T=\frac12\) and the optimal success is \(\frac34\). A computational-basis measurement achieves it: guess \(\ket0\) on outcome \(0\) (probability \(1\) for \(\ket0\), \(\frac12\) for \(I/2\)) and \(I/2\) on outcome \(1\). Success \(=\frac12(1)+\frac12(\frac12)=\frac34\). A mixed state can be partly distinguishable from a pure state that it contains.
Alice prepares \(\ket0\) with probability \(p_0=\frac34\) and \(\ket+\) with \(p_1=\frac14\). (a) Compute \(\Delta=p_0\ket0\bra0-p_1\ket+\bra+\) and its eigenvalues. (b) Find the optimal success probability. (c) Compare with always guessing \(\ket0\) and with the \(Z\) strategy of Section 8.1.1.
(a) \(\Delta=\begin{pmatrix}\frac58&-\frac18\\-\frac18&-\frac18\end{pmatrix}\), with trace \(\frac12\) and determinant \(-\frac{5}{64}-\frac{1}{64}=-\frac{3}{32}\). Its eigenvalues are \(\frac12\big(\frac12\pm\sqrt{\frac14+\frac38}\big)\approx0.645\) and \(-0.145\). (b) Success \(=p_1+\lambda_+\approx0.25+0.645=0.895\), equivalently \((1+\|\Delta\|_1)/2\). (c) Always guessing \(\ket0\) gives \(0.75\). The \(Z\) strategy gives \(\frac34\cdot1+\frac14\cdot\frac12=0.875\). The optimum beats both, but by less than with equal priors, because the prior already supplies much of the answer.
Bob receives \(n\) independent copies of either \(\ket0\) or \(\ket+\), with equal priors. (a) Show that the overlap of the two \(n\)-copy states is \(2^{-n/2}\). (b) Find the optimal success probability as a function of \(n\). (c) How many copies are needed to reach \(0.99\)?
Hint 1
The overlap of product states is the product of overlaps.
Hint 2
Success is \(\frac12\big(1+\sqrt{1-s^2}\big)\) with \(s^2=2^{-n}\).
Worked solution
(a) \(\braket{0^{\otimes n}}{+^{\otimes n}}=\big(\frac{1}{\sqrt2}\big)^n=2^{-n/2}\). (b) \(P_n=\frac12\big(1+\sqrt{1-2^{-n}}\big)\): \(0.854\), \(0.933\), \(0.968\), \(0.984\), \(0.992\) for \(n=1,\dots,5\). (c) \(n=5\) is the first to exceed \(0.99\). The error falls roughly by half with each additional copy. Independent copies are a resource the sender must supply; Bob cannot make them himself, because a cloner for \(\ket0\) and \(\ket+\) does not exist.
The unambiguous measurement uses \(E_0=c\ket-\bra-\), \(E_1=c\ket1\bra1\), and \(E_?=I-E_0-E_1\). (a) Write \(\ket-\bra-+\ket1\bra1\) as a matrix and find its largest eigenvalue. (b) Deduce the largest \(c\) for which \(E_?\) is positive. (c) What goes wrong if \(c\) is larger?
(a) The matrix \(\begin{pmatrix}\frac12&-\frac12\\-\frac12&\frac32\end{pmatrix}\) has trace \(2\) and determinant \(\frac34-\frac14=\frac12\), so its eigenvalues are \(1\pm\frac{1}{\sqrt2}\). (b) \(E_?=I-c(\cdots)\) has eigenvalues \(1-c(1\pm\frac{1}{\sqrt2})\), which are nonnegative exactly when \(c\le\frac{1}{1+1/\sqrt2}\). The text’s \(c\) is this largest value, which maximizes the conclusive probability. (c) A larger \(c\) gives \(E_?\) a negative eigenvalue, and a test along that direction would have negative probability. The constraint that effects remain positive is what limits unambiguous success to \(1-s\).
Compute the mutual information between the label and the outcome for the unambiguous measurement on equal-prior \(\ket0,\ket+\). Compare it with the values \(0.399\) bits (optimal decision basis) and \(0.311\) bits (\(Z\) measurement) found in Section 8.3.2.
Hint 1
A conclusive outcome identifies the label exactly; the inconclusive outcome is equally likely for both labels.
Hint 2
\(I(X:Y)=H(X)-H(X\mid Y)\).
Worked solution
Each label gives a conclusive result with probability \(1-\frac{1}{\sqrt2}\approx0.293\). A conclusive result leaves no uncertainty, and the inconclusive result has the same probability for both labels, so it leaves the prior \((\frac12,\frac12)\) and full uncertainty. Thus \(H(X\mid Y)=0.707\times1\) and \(I(X:Y)\approx0.293\) bits. That is less than both other measurements. Unambiguous discrimination is best when errors are unacceptable, not when the average information gained is the score: different tasks favor different measurements.
A student says: “The optimal measurement for \(\ket0\) versus \(\ket+\) succeeds \(85\%\) of the time, so on \(85\%\) of trials Bob knows the answer.” What does Bob actually know after one outcome? Contrast with the unambiguous measurement.
Hint 1
Compute Bob’s posterior probability for his guess after an outcome.
Hint 2
In the symmetric optimum, both labels have error \(q\approx0.146\).
Worked solution
After either outcome of the optimal measurement, Bob’s posterior probability that his guess is right is \(1-q\approx0.854\). He never learns on which trials he was right; every individual answer carries the same \(14.6\%\) risk. The \(85\%\) is a long-run fraction of correct guesses, not a fraction of trials with certainty. With the unambiguous measurement, a conclusive outcome gives posterior probability \(1\), on \(29\%\) of trials, and Bob knows exactly which trials those are. The two strategies offer different kinds of knowledge.
For pure states \(\ket\psi,\ket\phi\) with overlap magnitude \(s\) and priors \(p_0,p_1\), show that \(\Delta=p_0\ket\psi\bra\psi-p_1\ket\phi\bra\phi\) has trace \(p_0-p_1\) and determinant \(-p_0p_1(1-s^2)\) in their span. Deduce the optimal success \(\frac12\big(1+\sqrt{1-4p_0p_1s^2}\big)\), and check it against the worked problem with \(p_0=\frac34\).
Hint 1
In the basis \(\ket\psi,\ket{\psi_\perp}\), write \(\ket\phi=s\ket\psi+\sqrt{1-s^2}\ket{\psi_\perp}\).
Hint 2
\(\|\Delta\|_1=|\lambda_+|+|\lambda_-|=\sqrt{(\mathrm{tr})^2-4\det}\) when \(\det<0\).
Worked solution
In the basis \(\ket\psi,\ket{\psi_\perp}\), \(\Delta=\begin{pmatrix}p_0-p_1s^2&-p_1s\sqrt{1-s^2}\\-p_1s\sqrt{1-s^2}&-p_1(1-s^2)\end{pmatrix}\). Its trace is \(p_0-p_1\) and its determinant is \(-p_0p_1(1-s^2)\). With a negative determinant the eigenvalues have opposite signs, so \(\|\Delta\|_1=\sqrt{(p_0-p_1)^2+4p_0p_1(1-s^2)}=\sqrt{1-4p_0p_1s^2}\), using \((p_0-p_1)^2=1-4p_0p_1\). The success is \(\frac12(1+\sqrt{1-4p_0p_1s^2})\). For \(p_0=\frac34\), \(s^2=\frac12\): \(\sqrt{1-\frac38}\approx0.791\), giving \(0.895\), as computed directly.
With two copies of \(\ket0\) or \(\ket+\) (equal priors), the joint optimum is \(0.933\). (a) Suppose Bob measures each copy separately in the single-copy optimal basis, obtaining two independent guesses each wrong with probability \(q\approx0.146\), and then combines them. Show that the best combination still succeeds with only \(1-q\approx0.854\). (b) Find a better separate strategy using \(Z\) on both copies. (c) What does this suggest about measuring copies jointly?
Hint 1
When the two guesses disagree, either choice is right with probability \(\frac12\).
Hint 2
With \(Z\) on both copies, any outcome \(1\) proves the state was \(\ket+\).
Worked solution
(a) Both guesses are right with probability \((1-q)^2\); they disagree with probability \(2q(1-q)\), and then Bob is right half the time. Success \(=(1-q)^2+q(1-q)=1-q\approx0.854\): the second copy adds nothing. (b) Measuring \(Z\) on both and guessing \(\ket+\) if either outcome is \(1\) succeeds with probability \(\frac12\cdot1+\frac12\cdot\frac34=0.875\). (c) Both fall short of the joint optimum \(0.933\), which a measurement on the pair achieves. For two pure states it is known that measuring copies one at a time can also reach the optimum, provided each later measurement is chosen using earlier outcomes; fixed, independent measurements on the copies cannot.